#!/usr/bin/env python3
"""Reproduce Table 1 and run the predeclared AME sensitivity analyses.
Run from any directory: python3 /path/to/reproduce.py
Inputs: data/df.dta. Outputs: report.md, report.html, and robustness.svg beside this script.
Requires pandas, numpy, scipy, statsmodels, and pyreadstat (pandas Stata reader).
HTML generation also requires Pandoc.
"""
from pathlib import Path
from html import escape
import subprocess
import re
import numpy as np
import pandas as pd
from scipy import stats
import statsmodels.api as sm
ROOT = Path(__file__).resolve().parent
PAPER = "https://gborjas.scholars.harvard.edu/sites/g/files/omnuum4696/files/2026-01/sciadv.adz7173_0.pdf"
TITLE = "Reproduction and sensitivity analysis: Borjas and Breznau (2026)"
PREAMBLE = """## Robustness choices recorded before estimation
The fixed question is whether teams classified as pro-immigration produce higher average marginal effect (AME) estimates than teams classified as anti-immigration. I will report the adjusted pro-minus-anti contrast from Table 1, column 3, and compare the same contrast under eight defensible alternatives. For the sensitivity exercise, I will call the direction stable if the contrast remains positive, and the inferential conclusion stable if its two-sided 95% confidence interval excludes zero. These choices and expectations were written before running the reproduction or robustness models.
| Alternative choice | Reason an analyst might choose it | Expected effect on the headline conclusion, before estimation |
|---|---|---|
| 1. Give each reported model equal weight instead of each team equal total weight. | Treat every submitted specification as evidence, irrespective of team. | **May change it** because teams submitted very different numbers of models. |
| 2. Omit all covariates and estimate the raw pro-minus-anti difference. | Describe the observed association without model-based adjustment. | **May change it** because ideology and team characteristics may covary. |
| 3. Keep skill, topic experience, and team size but omit discipline indicators. | Avoid many indicators with only 71 independent teams. | **May change it** if discipline strongly confounds the association. |
| 4. Add the team's prior belief about the hypothesis. | Account for a related pre-analysis attitude. | Unlikely to change it materially, based on the paper's own supplementary result. |
| 5. Winsorise the model-level AME at its pooled 1st and 99th percentiles. | Reduce the influence of extreme submitted estimates while retaining all models. | **May change it** if the tails drive the mean. |
| 6. Trim model-level AMEs outside those same pooled percentile cutoffs, then recalculate inverse model-count weights within teams. | Exclude the most extreme submitted estimates. | **May change it** for the same reason; the number of retained teams will be checked. |
| 7. Replace each team's mean AME with its median and regress the 71 team medians on the baseline covariates. | Describe a team's typical rather than average submitted finding. | **May change it** if a few within-team results drive team means. |
| 8. Refit the baseline after deleting each team in turn, and report the smallest pro-minus-anti contrast. | Check dependence on any single team, especially among nine anti-immigration teams. | **May change it**, particularly its confidence interval. The deletion rule is fixed here, before inspecting influence. |
"""
def design(frame, ideology="groups", controls="full", prior=False):
parts = []
if ideology == "index":
parts.append(frame[["proindex"]].astype(float))
elif ideology == "shares":
parts.append(frame[["p12", "p56"]].astype(float))
else:
parts.append(frame[["group1", "group3"]].astype(float))
if prior:
parts.append(frame[["pbelief"]].astype(float))
if controls != "none":
parts.append(frame[["stats_brw", "topic_brw", "t2", "t3"]].astype(float))
if controls == "full":
degree = pd.Categorical(frame["mdegree"])
dummies = pd.get_dummies(degree, prefix="degree", drop_first=True, dtype=float)
dummies.index = frame.index
parts.append(dummies)
return sm.add_constant(pd.concat(parts, axis=1), has_constant="add")
def fit(frame, outcome="ame", ideology="groups", controls="full", prior=False,
weights="team", covariance="cluster"):
x = design(frame, ideology, controls, prior)
y = frame[outcome].astype(float)
if weights == "team":
w = 1 / frame.groupby("teamid")["teamid"].transform("size").astype(float)
elif weights == "model":
w = pd.Series(1.0, index=frame.index)
else:
raise ValueError(weights)
used = pd.concat([x, y.rename("response"), w.rename("weight"), frame["teamid"]], axis=1).dropna()
if covariance == "cluster":
result = sm.WLS(used.response, used[x.columns], weights=used.weight).fit(
cov_type="cluster", cov_kwds={"groups": used.teamid, "use_correction": True})
elif covariance == "HC3":
result = sm.WLS(used.response, used[x.columns], weights=used.weight).fit(cov_type="HC3")
else:
raise ValueError(covariance)
return result, int(used.teamid.nunique()), len(used)
def linear_combo(result, teams, terms, covariance="cluster"):
vector = pd.Series(0.0, index=result.params.index)
for term, coefficient in terms.items():
vector[term] = coefficient
est = float(vector @ result.params)
se = float(np.sqrt(vector @ result.cov_params() @ vector))
df = teams - 1 if covariance == "cluster" else result.df_resid
critical = stats.t.ppf(0.975, df)
p = 2 * stats.t.sf(abs(est / se), df)
return {"estimate": est, "se": se, "low": est - critical * se,
"high": est + critical * se, "p": p}
def contrast(frame, **kwargs):
covariance = kwargs.get("covariance", "cluster")
result, teams, models = fit(frame, **kwargs)
out = linear_combo(result, teams, {"group3": 1, "group1": -1}, covariance)
return {**out, "teams": teams, "models": models}
def f3(value):
if abs(value) < 0.0005:
value = 0.0
return f"{value:.3f}"
def svg_figure(rows):
width, height = 1120, 440
left, right = 300, 800
all_bounds = [v for row in rows for v in (row["low"], row["high"])]
minimum = min(-0.06, min(all_bounds) - 0.015)
maximum = max(0.20, max(all_bounds) + 0.015)
project = lambda value: left + (value - minimum) / (maximum - minimum) * (right - left)
items = [f'')
(ROOT / "robustness.svg").write_text("\n".join(items) + "\n")
def render_html(markdown_text, abstract):
"""Render the generated report as a standalone, locally readable HTML page."""
section = "## Robustness choices recorded before estimation"
body_markdown = section + markdown_text.split(section, 1)[1]
rendered = subprocess.run(
["pandoc", "--from=gfm", "--to=html", "--wrap=none"],
input=body_markdown, text=True, capture_output=True, check=True,
).stdout
rendered = rendered.replace("
"""
(ROOT / "report.html").write_text(page)
def main():
data = pd.read_stata(ROOT / "data" / "df.dta", convert_categoricals=False)
data = data.loc[data.teamid.notna()].copy()
assert len(data) == 1253 and data.teamid.nunique() == 71
assert data.groupby("teamid")[["group1", "group2", "group3"]].first().sum().tolist() == [9, 31, 31]
assert np.all(data.groupby("teamid").nmodel.first() == data.groupby("teamid").size())
assert data[["ame", "neg10s", "pos10s", "group1", "group3", "stats_brw", "topic_brw", "mdegree"]].notna().all().all()
# Entries transcribed from the opened, author-hosted article PDF, Table 1.
published = {
("AME", "index"): (0.011, 0.006), ("AME", "shares"): (0.074, 0.024),
("AME", "groups"): (0.085, 0.031),
("Negative tail", "index"): (-0.051, 0.021), ("Negative tail", "shares"): (-0.242, 0.107),
("Negative tail", "groups"): (-0.274, 0.125),
("Positive tail", "index"): (0.019, 0.012), ("Positive tail", "shares"): (0.114, 0.045),
("Positive tail", "groups"): (0.087, 0.035),
}
table_rows = []
for outcome_name, outcome in [("AME", "ame"), ("Negative tail", "neg10s"), ("Positive tail", "pos10s")]:
for ideology, label, term, col in [
("index", "Mean sentiment, per scale point", {"proindex": 1}, 1),
("shares", "Pro minus anti team fraction", {"p56": 1, "p12": -1}, 2),
("groups", "Pro minus anti team category", {"group3": 1, "group1": -1}, 3),
]:
result, teams, models = fit(data, outcome=outcome, ideology=ideology)
comp = linear_combo(result, teams, term)
published_est, published_se = published[(outcome_name, ideology)]
table_rows.append((outcome_name, label, col + (0 if outcome_name == "AME" else 3 if outcome_name == "Negative tail" else 6), published_est, published_se, comp, teams, models))
rows = [{"label": "Published specification", **contrast(data)}]
alternatives = [
("Equal model weight", contrast(data, weights="model")),
("No covariates", contrast(data, controls="none")),
("No discipline indicators", contrast(data, controls="short")),
("Add prior belief", contrast(data, prior=True)),
]
lower, upper = data.ame.quantile([0.01, 0.99]).tolist()
winsor = data.copy()
winsor["ame"] = winsor.ame.clip(lower, upper)
alternatives.append(("Winsorised AME", contrast(winsor)))
trimmed = data.loc[data.ame.between(lower, upper)].copy()
alternatives.append(("Trimmed AME", contrast(trimmed)))
median = data.groupby("teamid", as_index=False).first()
median["ame"] = data.groupby("teamid").ame.median().to_numpy()
alternatives.append(("Team median AME", contrast(median, covariance="HC3")))
deleted = [(team, contrast(data.loc[data.teamid != team])) for team in sorted(data.teamid.unique())]
deleted_team, worst = min(deleted, key=lambda item: item[1]["estimate"])
leave_one_min = min(result["estimate"] for _, result in deleted)
leave_one_max = max(result["estimate"] for _, result in deleted)
leave_one_positive = sum(result["estimate"] > 0 for _, result in deleted)
leave_one_ci_positive = sum(result["low"] > 0 for _, result in deleted)
alternatives.append(("Minimum leave-one-team-out", worst))
rows.extend({"label": label, **result} for label, result in alternatives)
svg_figure(rows)
stable_direction = sum(row["estimate"] > 0 for row in rows)
stable_ci = sum(row["low"] > 0 for row in rows)
abstract = (f"The adjusted pro-minus-anti-immigration team AME difference is "
f"{f3(rows[0]['estimate'])} (95% CI {f3(rows[0]['low'])} to {f3(rows[0]['high'])}), "
f"matching the published result. All eight predeclared alternative estimates remain positive, "
f"but only {stable_ci-1} have 95% intervals excluding zero. The association is consistent in "
"direction, while its precision depends on defensible analysis choices and does not establish causation.")
lines = [f"# {TITLE}\n", "**Prepared by Codex GPT-6-Sol**\n", "## Abstract\n", abstract + "\n", PREAMBLE, "\n## Main result\n",
f"I used the supplied `data/df.dta` and reproduced the nine key Table 1 estimates. The input has {len(data):,} usable model records from {data.teamid.nunique()} teams: {int(data.groupby('teamid').group1.first().sum())} anti-immigration, {int(data.groupby('teamid').group2.first().sum())} moderate, and {int(data.groupby('teamid').group3.first().sum())} pro-immigration teams. One extra `.dta` record has no team ID or AME and is excluded. Table 1 regressions give each team equal total weight and cluster standard errors by team. The negative and positive tail outcomes use the indicators already supplied in the dataset.\n",
"| Outcome | Ideology contrast | Published estimate (SE) | Reproduced estimate (SE) | Reproduced 95% CI | Published source |",
"|---|---|---:|---:|---:|---|"]
for outcome_name, label, col, pub_est, pub_se, comp, _, _ in table_rows:
lines.append(f"| {outcome_name} | {label} | {f3(pub_est)} ({f3(pub_se)}) | {f3(comp['estimate'])} ({f3(comp['se'])}) | [{f3(comp['low'])}, {f3(comp['high'])}] | [Paper PDF, Table 1, col. {col}]({PAPER}) |")
lines.extend(["\nThe AME category contrast is the headline comparison: pro-immigration teams have higher adjusted AMEs than anti-immigration teams. All nine point estimates agree with the paper at three decimal places. Eight of nine standard errors do too; for the positive-tail team-fraction contrast (column 8), the paper prints 0.045, while the package's `code/Log Files/02_Main_Regs.log` gives 0.0458145 and this calculation rounds to 0.046. The tail results are linear probability contrasts; a value of 0.087 represents 8.7 percentage points.\n",
"## Robustness of the AME category contrast\n",
"| Analysis | Pro minus anti | SE | 95% CI | Two-sided p | Teams | Models |",
"|---|---:|---:|---:|---:|---:|---:|"])
for row in rows:
lines.append(f"| {row['label']} | {f3(row['estimate'])} | {f3(row['se'])} | [{f3(row['low'])}, {f3(row['high'])}] | {f3(row['p'])} | {row['teams']} | {row['models']:,} |")
lines.extend(["\n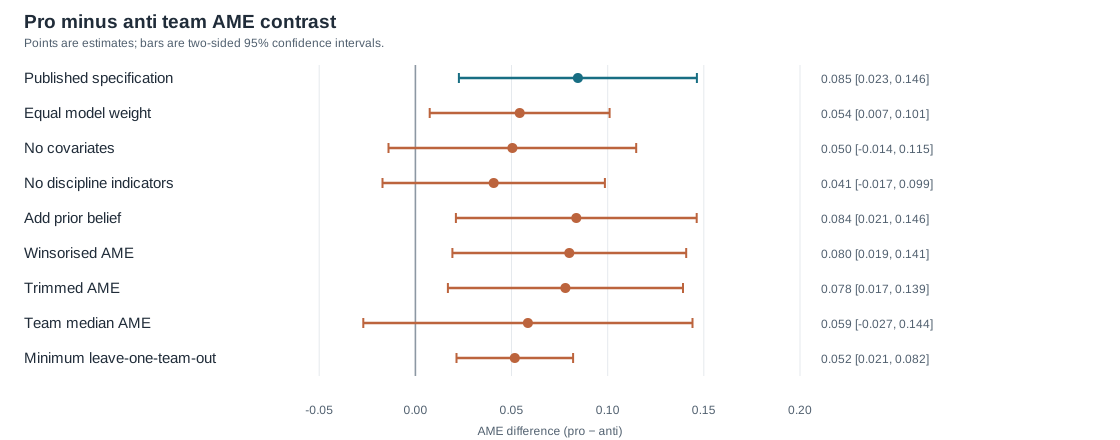\n",
"[Open the figure at full size](robustness.svg)\n",
f"The pooled AME cutoffs for winsorisation and trimming are {f3(lower)} and {f3(upper)}. Across all {len(deleted)} single-team deletions, the contrast ranges from {f3(leave_one_min)} to {f3(leave_one_max)}; {leave_one_positive} remain positive and {leave_one_ci_positive} have 95% intervals above zero. The minimum occurs on deleting team {int(deleted_team)} ({'anti' if data.loc[data.teamid.eq(deleted_team), 'group1'].iloc[0] == 1 else 'pro' if data.loc[data.teamid.eq(deleted_team), 'group3'].iloc[0] == 1 else 'moderate'}-immigration). Each trimmed team's weight was recalculated as the inverse of its retained model count. The median analysis uses one record per team and HC3 standard errors; other rows use model-level weighted least squares and team-clustered standard errors.\n",
"## Analysis decisions left open by the paper\n",
"- I chose Table 1's AME category contrast as the numerical headline. The paper also emphasises the continuous ideology and tail outcomes, reproduced above.\n",
"- I began with the package's prepared `df.dta` rather than rebuilding it from the raw survey and model files. Thus, this reproduction accepts its team classification, skill and topic scores, discipline coding, and imputations. For the tail models, I used the package's existing indicators rather than reconstructing percentiles and significance tests.\n",
"- I excluded the record without a team ID or AME to match the paper's analysis sample. The supplied `nmodel` matches the actual number of model records per team.\n",
"- To implement the paper's weighted regressions in Python, I used weighted least squares, the lowest observed `mdegree` code as the categorical reference, a finite-sample cluster covariance correction, and t critical values with teams minus one degrees of freedom. The reference code affects individual discipline coefficients but not the reported ideology contrasts.\n",
"- I set a two-sided 95% interval as the threshold for the sensitivity conclusion and set the pooled, unweighted model-level 1st and 99th percentiles as the cutoffs for trimming and winsorisation. Within trimmed data I recalculated team weights. For team medians I used HC3 intervals.\n",
"- The prespecified deletion diagnostic reports the smallest pro-minus-anti contrast across single-team removals; its p value is descriptive rather than a new confirmatory test.\n",
"## Reproducibility and interpretation\n",
"Run `python3 reproduce.py` from a clean Python session with `pandas`, `numpy`, `scipy`, `statsmodels`, and `pyreadstat` installed, plus Pandoc for HTML conversion. The script reads only `data/df.dta` and writes `report.md`, `report.html`, and `robustness.svg`. The nine published numbers and standard errors in the comparison table are transcribed from the paper PDF; all reproduced and sensitivity estimates, intervals, p values, sample counts, cutoffs, and figure coordinates are computed by this script.\n"])
lines.extend(["## Conclusion\n",
f"The adjusted pro-minus-anti AME difference reproduces the published result at its reported precision, and its direction stays positive in {stable_direction} of {len(rows)} specifications. The two-sided 95% interval excludes zero in {stable_ci} of {len(rows)} specifications ({stable_ci-1} of eight alternatives), so the strength of evidence depends on reasonable analysis choices. These are observational associations across teams, with only nine anti-immigration teams, and do not by themselves establish that ideology caused the different estimates.\n"])
markdown_text = "\n".join(lines)
(ROOT / "report.md").write_text(markdown_text)
render_html(markdown_text, abstract)
print(f"Wrote {ROOT / 'report.md'}, {ROOT / 'report.html'}, and {ROOT / 'robustness.svg'}")
if __name__ == "__main__":
main()
